Label-Free Text Prototype Adaptation for Open Vocabulary Segmentation.- Driving is a Game: Combining Planning and Prediction with Bayesian Iterative Best Response.- Guardrail-Agnostic Societal Bias Evaluation in Large Vision-Language Models.- AMCoNav: Asynchronous Multi-module Collaborative Framework for Embodied Visual Navigation.- Dynamic Inverse Rendering for Enhanced Material-Lighting Decomposition.- CabinSI: Omni-Cabin Spatial Reasoning through Explicit Visual Cognitive Maps.- Geometry-Aware Single-Image 4D Synthesis via Dense Trajectory Generation.- SpatiO: Adaptive Test-Time Orchestration of Vision-Language Agents for Spatial Reasoning.- One Trap to Block Them All: Defending Encoder Stealing via Isotropic Uniformity.- SMG: Semantic Motion Graph for Monocular Dynamic Gaussian Splatting.- Causal Intervention in Concept Bottleneck Models.- AnyMatch: Supercharging Universal Multi-Modal Image Matching with Large-Scale Single-View Images.- Starve to Perceive: Taming Lazy Perception in VLMs with Constrained Visual Bandwidth.- Flow Straight to Reality: Perceptually Consistent Flow Matching for Efficient Image Restoration.- MedSPOT: A Workflow-Aware Sequential Grounding Benchmark for Clinical GUI.- OCA: ODE-Driven Cross-Attention for Image-to-Point-Cloud Registration.- Training-free Controllable Motion Generation under Heterogeneous Constraints.- SPARC: Scalable Path-Specific Counterfactual Fairness via Causal Conditional Independence.- DriveVA: Video Action Models are Zero-Shot Drivers.- Fast and High-Quality Vision-Language Grounding with Parallel Box Decoding.- EraseSAE: Surgical Concept Erasure in Text-to-Video Diffusion Models via Sparse Autoencoders.- Sticking Information in Plain Sight: Encoding and Detecting Hidden Stickers in the Real World.- LogicIR: Logic Gate Networks for Image Restoration.- HHA: Hierarchical Hyperbolic Constraints for Imperceptible Point Cloud Attacks.- VLMSysTrojan: Stealthy System-Aware Backdoor Attacks Against Vision-Language Models.- Unified Video Dense Prediction from Disjoint Data.- WorldAgents: Can Foundation Image Models be Agents for 3D World Models?.- ReconPhys: Reconstruct Appearance and Physical Attributes from Single Video.- AC3S: Adaptive Conditioning for 3D-Aware Synthetic Data Generation.- MedGSSR: Generalizable Medical Image Super-Resolution 3D Reconstruction via Hierarchical Feed-forward Gaussian Splatting.- ART-VSR: Adaptive Rectified Trajectories for One-Step Video Super-Resolution.- Reconstructing Dense Depth of Dark Scenes with Sparse LiDAR, Noisy Events, and Blurry RGB.- TARS: MinMax Token-Adaptive Preference Strategy for Hallucination Reduction in MLLMs.- SDSA: Shallow-Deep Squeezing Adapter for Vision-Language Models.- RePlan: Reasoning-Guided Region Planning for Complex Instruction-Based Image Editing.- High-speed Imaging through Turbulence with Event-based Light Fields.- ATP-Bench: Towards the Agentic Tool Planning for MLLM Interleaved Generation.- Pixel-wise Planarity for High-Precision Monocular Plane Segmentation.
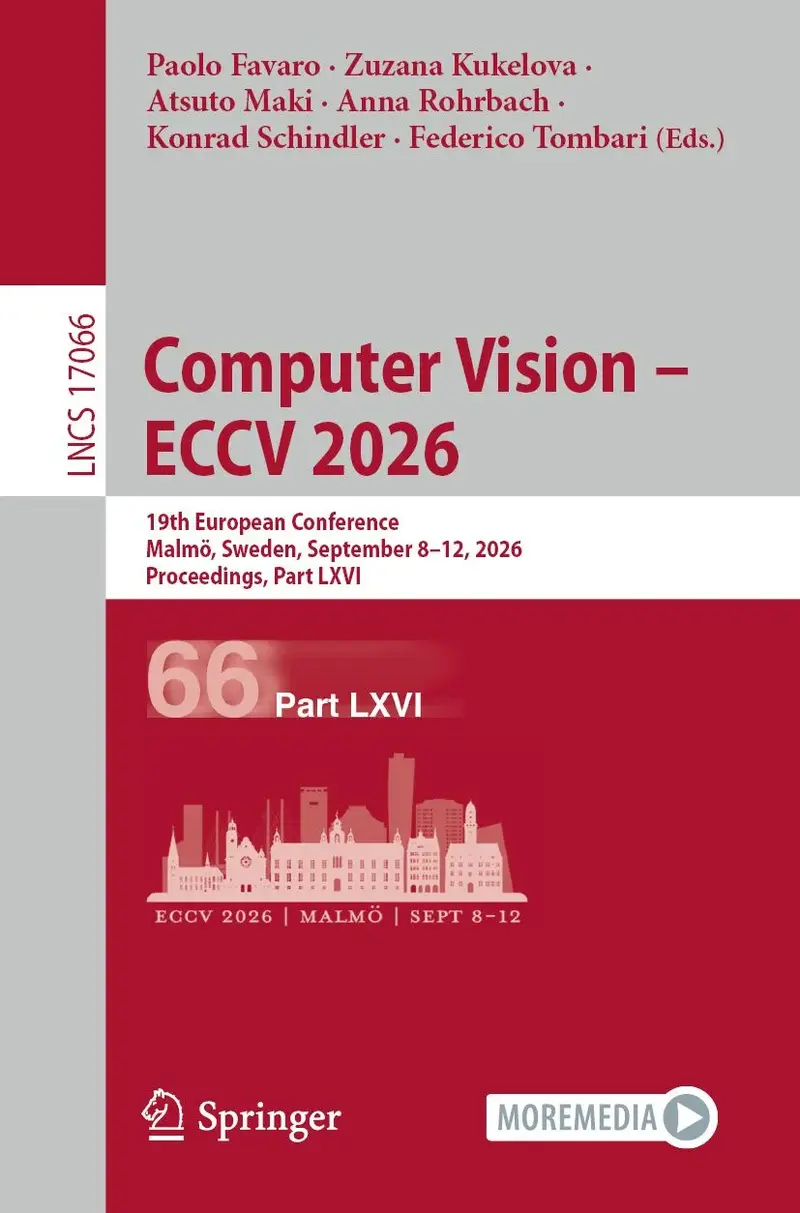
Computer Vision – ECCV 2026
Ursprünglicher Preis war: 53,49 €37,44 €Aktueller Preis ist: 37,44 €.
📍 -- Personen haben dieses Produkt kürzlich angesehen
🚚 Voraussichtliche Lieferung: Okt. 14 - Okt. 19
📦 Versandrichtlinie: Kostenloser Versand bei Bestellungen über 25 €
🛡️ 30-Tage-Rückgabe: Kostenlose Rücksendung, keine Wiederaufnahmegebühren
✉️ Kundensupport: 24/7 Unterstützung
🔒 Sicherer Checkout
Ähnliche Produkte
-
E-Book
Robotics and Mechatronics
Ursprünglicher Preis war: 298,53 €223,90 €Aktueller Preis ist: 223,90 €. In den Warenkorb -
E-Book
Computational Science and Its Applications – ICCSA 2026 Workshops
Ursprünglicher Preis war: 53,49 €37,44 €Aktueller Preis ist: 37,44 €. In den Warenkorb -
E-Book
A Century of Cosmic Discoveries
Ursprünglicher Preis war: 117,69 €88,27 €Aktueller Preis ist: 88,27 €. In den Warenkorb -
E-Book
Obstetrics
Ursprünglicher Preis war: 748,99 €300,00 €Aktueller Preis ist: 300,00 €. In den Warenkorb
Rezensionen
Es gibt noch keine Rezensionen.