C2E: Boosting Ego-Only 3D Object Detection via Multi-Teacher Contrastive Knowledge Distillation.- Break Visual-Linguistic Asymmetry: Unleashing VLM’s Cross-Modal Potential for General Face Forgery Detection.- AutoSpeed: Annotation-Free Stage-Adaptive Motion Speed Learning for Robot Manipulation.- From Blobs to Spokes: High-Fidelity Surface Reconstruction via Oriented Gaussians.- DART: Difficulty-Adaptive Routing for Zero-Shot Video Temporal Grounding.- OmniHuman: A Large-scale Dataset and Benchmark for Human-Centric Video Generation.- UECP: Uncertainty-Enhanced Collaborative Perception.- Retrieving and Refining Winning Noise Tickets for Diffusion-Based Motion Generation.- When Sinks Help or Hurt: Unified Framework for Attention Sink in MLLMs.- TAQ: Static-Deployable Temporal-Aware Quantization for Real-World Video Super-Resolution.- EGVLR: Evidence-Grounded Vision–Language Reinforcement for Anomaly Reasoning.- SVI-Bench: A Dynamic Microworld for Strategic Video Intelligence.- Bayesian Uncertainty Attribution-Guided Fine-Tuning for Open-Set Action Recognition.- Resolution-Agnostic Neural Operators for Multi-Rate Sparse-View CT.- BeyondSight: Object Permanence for End-to-End Autonomous Driving.- MCPNet:Masked Coordinate Pooling-based Attention Network for Medical Landmark Detection.- Consistent Feature Transport for Image Relighting.- Structured SIR: Efficient and Expressive Importance-Weighted Inference for High-Dimensional Image Registration.- LivingWorld: Interactive 4D World Generation with Environmental Dynamics.- Robust onion: Peeling Open Vocab Object Detectors Under Noise.- Co-evolving Representations in Joint Image-Feature Diffusion.- PeCA: Palette Context Assisted Inference for Test-Time Paint-Bucket Colourisation on Animation Videos.- Memory-Supported Synergistic Adaptation for Training-Free Test-Time Medical Image Segmentation.- Prosthesis-Aware 3D Human Pose Estimation: A Dataset and Benchmark for RSP Users.- AHOY! Animatable Humans under Occlusion from YouTube Videos with Gaussian Splatting and Video Diffusion Priors.- Concept-as-Tree: A Controllable Synthetic Data Framework Makes Stronger Personalized VLMs.- Vulnerability of Privacy-Preserving Visual Localization against Diffusion-based Attacks.- LENS: Adaptive Spatio-Temporal Zooming for Keyframe Sampling in Long-Form Videos.- NanoGS: Training-Free and Lightweight Gaussian Splat Simplification.- Keeping the Evidence Chain: Semantic Evidence Allocation for Training-Free Token Pruning in Video Temporal Grounding.- BeTTER: Diagnose the Illusion of Embodied Reasoning in Vision-Language-Action Models.- Continuous Heart Rate Variability Estimation from Egocentric Systems for Skill Assessment.- Video-Oasis: Rethinking Evaluation of Video Understanding.- TPCNet: A Low-Light Image Enhancement Network Inspired by Triple Physical Constraints.- Swap the Right Identity: Spatio-Temporal Preference Optimization for Identity Swapping.- EcoVideo: Entropy-Orchestrated Video Generation Paradigm in Cloud-Edge Dynamics.- CLIP-AUTT: Test-Time Personalization with Action Unit Prompting for Fine-Grained Video Emotion Recognition.
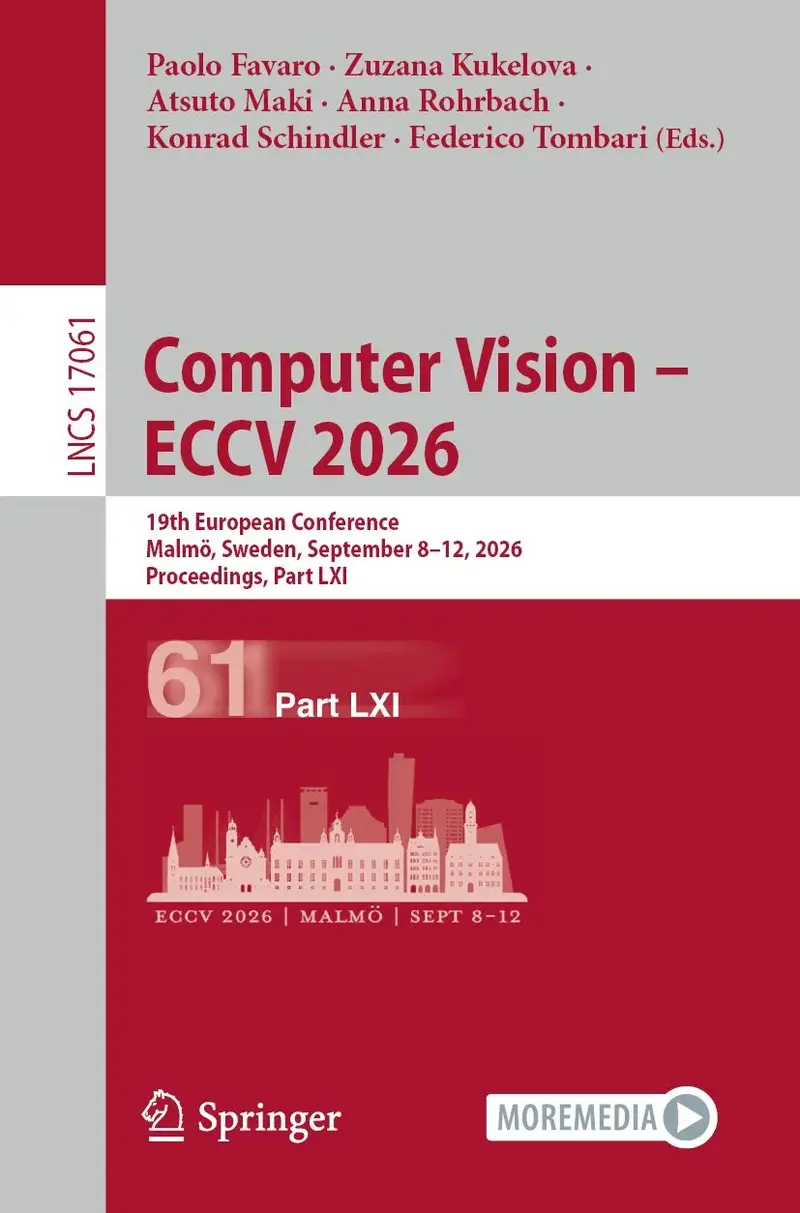
Computer Vision – ECCV 2026
Ursprünglicher Preis war: 96,29 €67,40 €Aktueller Preis ist: 67,40 €.
📍 -- Personen haben dieses Produkt kürzlich angesehen
🚚 Voraussichtliche Lieferung: Okt. 14 - Okt. 19
📦 Versandrichtlinie: Kostenloser Versand bei Bestellungen über 25 €
🛡️ 30-Tage-Rückgabe: Kostenlose Rücksendung, keine Wiederaufnahmegebühren
✉️ Kundensupport: 24/7 Unterstützung
🔒 Sicherer Checkout
Ähnliche Produkte
-
E-Book
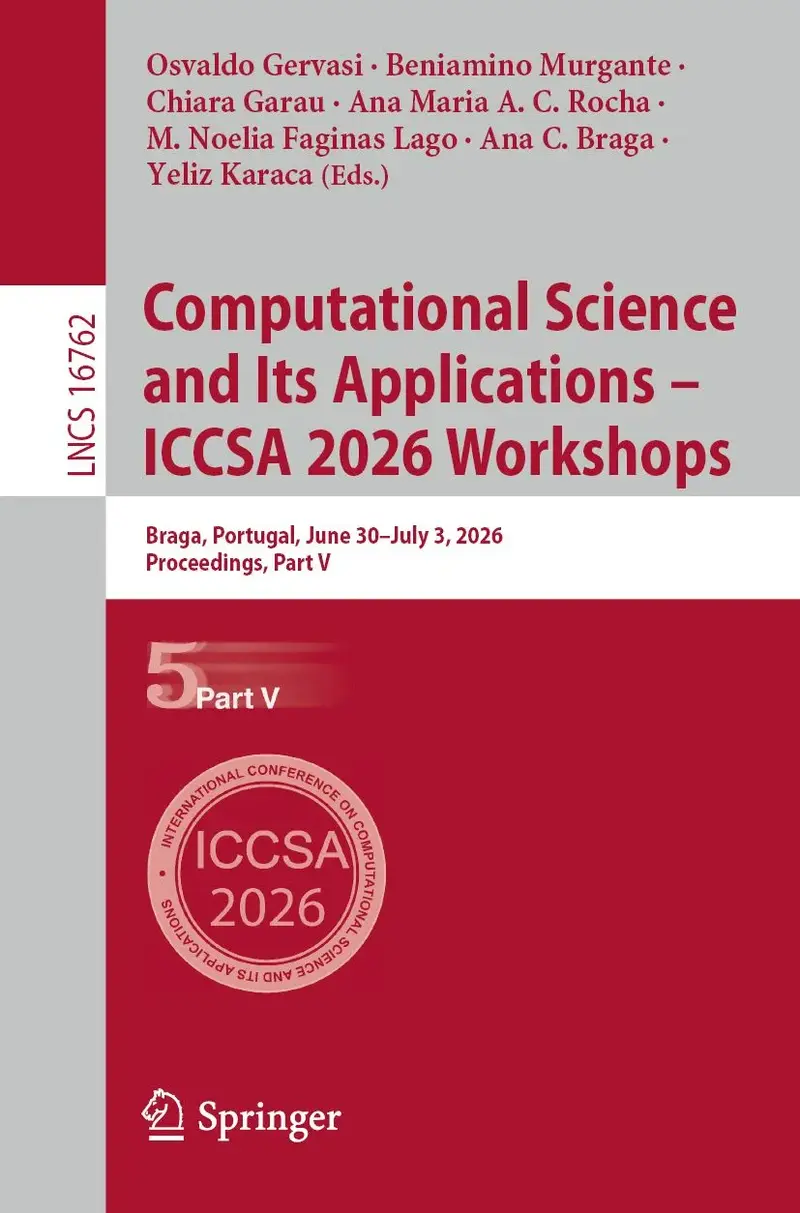
Computational Science and Its Applications – ICCSA 2026 Workshops
Ursprünglicher Preis war: 53,49 €37,44 €Aktueller Preis ist: 37,44 €. In den Warenkorb -
E-Book
Amerika ’33
Ursprünglicher Preis war: 22,99 €16,09 €Aktueller Preis ist: 16,09 €. In den Warenkorb -
E-Book
Gemeinsam Versorgungsqualität stärken
Ursprünglicher Preis war: 39,99 €27,99 €Aktueller Preis ist: 27,99 €. In den Warenkorb -
E-Book
HCI International 2026 Posters
Ursprünglicher Preis war: 117,69 €88,27 €Aktueller Preis ist: 88,27 €. In den Warenkorb
Rezensionen
Es gibt noch keine Rezensionen.