VD-LoRA: Adaptive Reuse of Low-Rank Directions for Continual Learning.- Stylized Video Generation via Decoupled Data Synthesis and Gated Style Token Injection.- RawGen: Learning Camera Raw Image Generation.- Color Pass-Through via Camera-Display Coupling.- Video Generation Models Are Inherent Lighting Estimators.- ZMIS-SAM: Segment Anything Model Enhanced With Wavelet Transform For Zooplankton Microscopy Image Instance Segmentation.- VIGA: View-Conditioned and Identity-Guided Adaptation for Aerial-Ground Person Re-Identification.- ProMSA:Progressive Multimodal Search Agents for Knowledge-Based Visual Question Answering.- EgoEverything: A Benchmark for Human Behavior–Inspired Long-Context Egocentric Video Understanding in AR Environment.- AnyFlow: Any-Step Video Diffusion Model with On-Policy Flow Map Distillation.- DIGS: Differentiable, Incremental, Global, Scalable Pruning for Language Models.- PhysConvex: Physics-Informed Dynamic Convex Fields for Reconstruction and Simulation.- Objects as Audio-Visual Modal Sound Fields.- Reweighting Framewise Attention in Video Transformers for Facial Emotion Recognition.- Generation Models Know Space: Unleashing Implicit 3D Priors for Scene Understanding.- RADIANCE: Relative Adaptive Denoising with IP-Adapter for Novel Concept Enhancement.- Unlocking Complex Image Editing via Natively Interleaved Visual Textual CoT with Deep Confidence Reasoning.- Towards Sparsely Annotated Open World Object Detection.- OmniX: Any-view and Any-time 4D reconstruction via Feed-forward Trajectory Fields.- MSVS-VAE: Multi-Scale Anchored VecSet for High-Fidelity 3D Reconstruction.- Aligning Anything: Hierarchical Motion Estimation for Video Frame Interpolation.- TanGO: Training-Free 3D Editing via Tangent-Space Guidance and Optimization.- ReQuest: Rethinking-based Question-Aware Frame Selection for Long-Form Video QA.- Active View Selection with Perturbed Gaussian Ensemble for Tomographic Reconstruction.- SpaMEM: Benchmarking Dynamic Spatial Reasoning via Perception–Memory Integration in Embodied Environments.- InFlux++: Real and Synthetic Data for Estimating Dynamic Camera Intrinsics.- Capturing Spectral and Spatial Patterns for Federated Remote Sensing Segmentation.- Boosting 3D Foundation Models with Featureless Pose Optimization.- Doe-2: 3D Representation World Model for Unified Driving Scene Forecasting.- ProactiveBench: Benchmarking Proactiveness in Multimodal Large Language Models.- CASA: Cross-Attention over Self-Attention for Efficient Vision-Language Fusion.- Continuous Speculative Decoding for Autoregressive Image Generation.- H-Adapter: Pose-Robust Hairstyle Transfer via Attention-Derived, Source-Aligned Hair Masks.- PLOT: Pseudo-Labeling via Object Tracking for Monocular 3D Object Detection.- Domain Generalization via Text-Anchored Information Bottleneck.- There and Back Again: A Flexible-Frame Transformer for Multi-Exposure Fusion.- Difficulty-Conditioned Attribute-Specific Restoration for Low-Light Image Enhancement.- Proximity-CLIP: Text-Guided Semantic Proximity Learning for Zero-Shot Anomaly Detection.
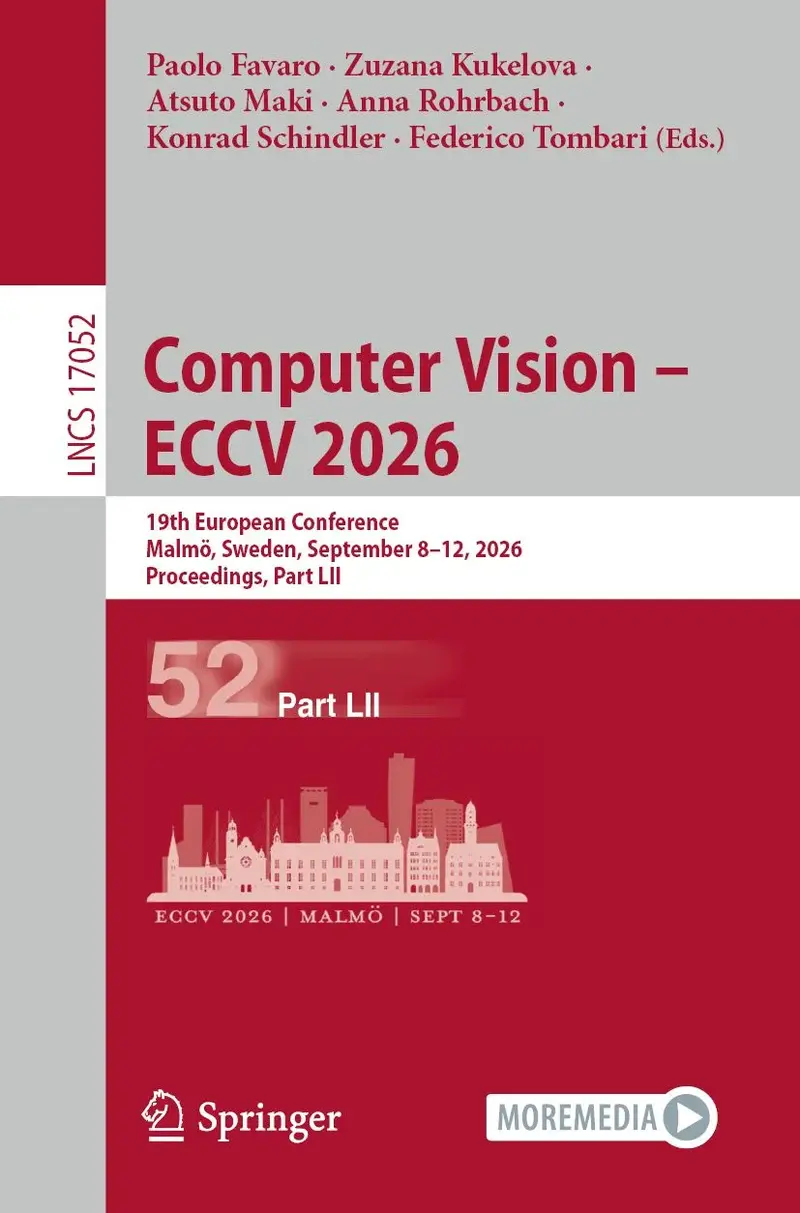
Computer Vision – ECCV 2026
Ursprünglicher Preis war: 96,29 €67,40 €Aktueller Preis ist: 67,40 €.
📍 -- Personen haben dieses Produkt kürzlich angesehen
🚚 Voraussichtliche Lieferung: Okt. 14 - Okt. 19
📦 Versandrichtlinie: Kostenloser Versand bei Bestellungen über 25 €
🛡️ 30-Tage-Rückgabe: Kostenlose Rücksendung, keine Wiederaufnahmegebühren
✉️ Kundensupport: 24/7 Unterstützung
🔒 Sicherer Checkout
Ähnliche Produkte
-
E-Book
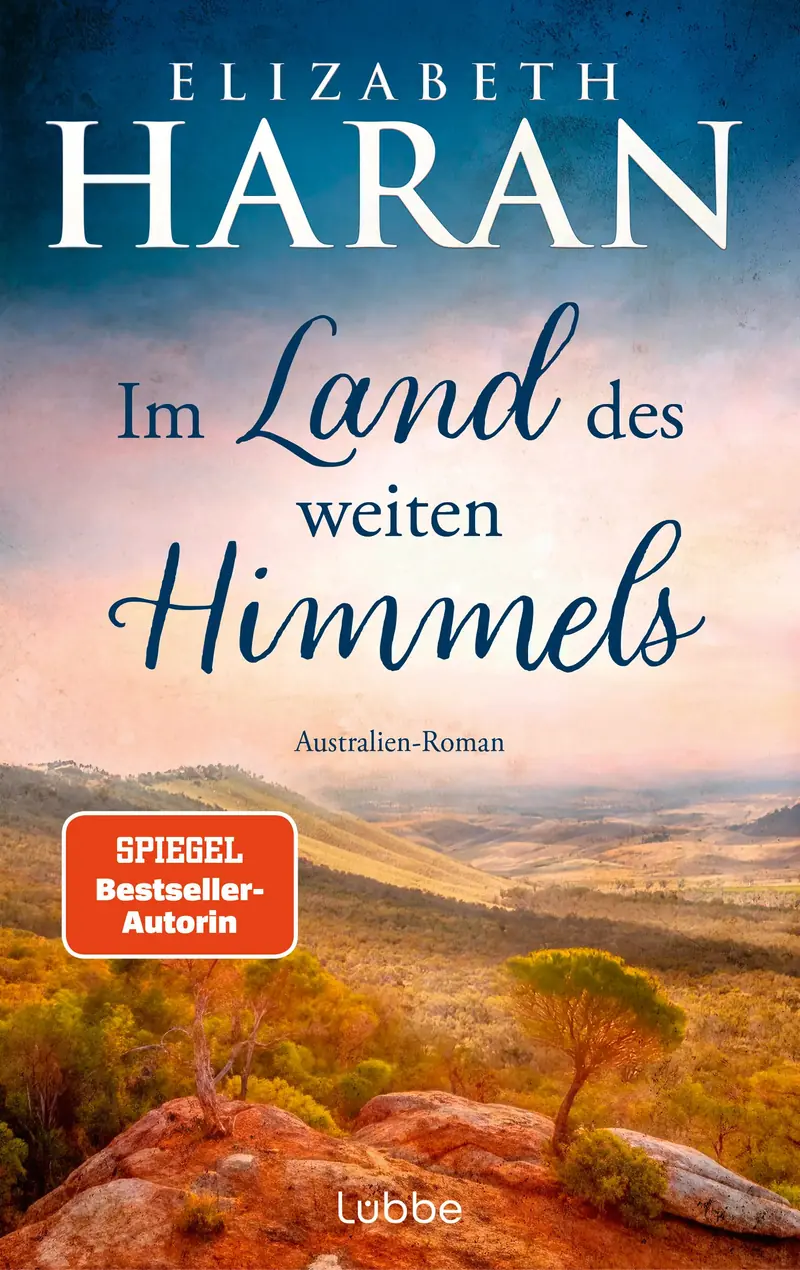
Im Land des weiten Himmels
Ursprünglicher Preis war: 14,99 €10,49 €Aktueller Preis ist: 10,49 €. In den Warenkorb -
E-Book
Das schwimmende Café von Kopenhagen
Ursprünglicher Preis war: 9,99 €6,99 €Aktueller Preis ist: 6,99 €. In den Warenkorb -
E-Book
A Century of Cosmic Discoveries
Ursprünglicher Preis war: 117,69 €88,27 €Aktueller Preis ist: 88,27 €. In den Warenkorb -
E-Book
Robotics and Mechatronics
Ursprünglicher Preis war: 298,53 €223,90 €Aktueller Preis ist: 223,90 €. In den Warenkorb
Rezensionen
Es gibt noch keine Rezensionen.